Shaping control
Current coarse observations and 1.7-yard lateral / 1.8-yard depth target offsets. Potential shaping rewards positioning progress alongside the existing win/loss outcome.
BEHAVIOR LAB / 05 — FREE MOVEMENT
Three variants. Five fresh seeds each.
The QB line is a reference, never a movement wall.
01 / BEST CHECKPOINTS, UNSEEN TESTS
Loading completed experiment…
| Variant | G wins ↑ | Seed range | Lane coverage ↑ | Wrong-way motion ↓ |
|---|
Means and standard deviations are across five independent training seeds. The same held-out scenarios are shared across variants and seeds. Checkpoints are chosen by validation wins only; these test results never choose the checkpoint. Lane coverage means G is between DT and QB and within 0.8 yd of their connecting line. Wrong-way motion measures free-movement time traveling laterally away from that line while misaligned. These are geometry proxies, not NFL technique scores.
| G wins · best checkpoint | A · Control | B · Observations | C · Finer control |
|---|
02 / MATCHED SCENARIOS
Each card faces the same DT plan, starting positions, QB depth and initial random seed. Learned openings and movement can differ. Choose the same training seed to compare the variants fairly. Replay never trains the players.
Every rep starts at the line of scrimmage. The DT lines up on the defensive side. If it reaches or passes the QB’s yardage, the guard keeps tracking it and can recover behind the pocket.
GUARDDTQBDashed diagonal: rush lane · Blue horizontal: QB lineTrails: player movementPositive G depth: behind the QB
Loading saved policies…
Download links include the variant and engine identity. Use these bundles with this study viewer; the main lab’s save format has different observation semantics.
03 / CHECKPOINT SELECTION
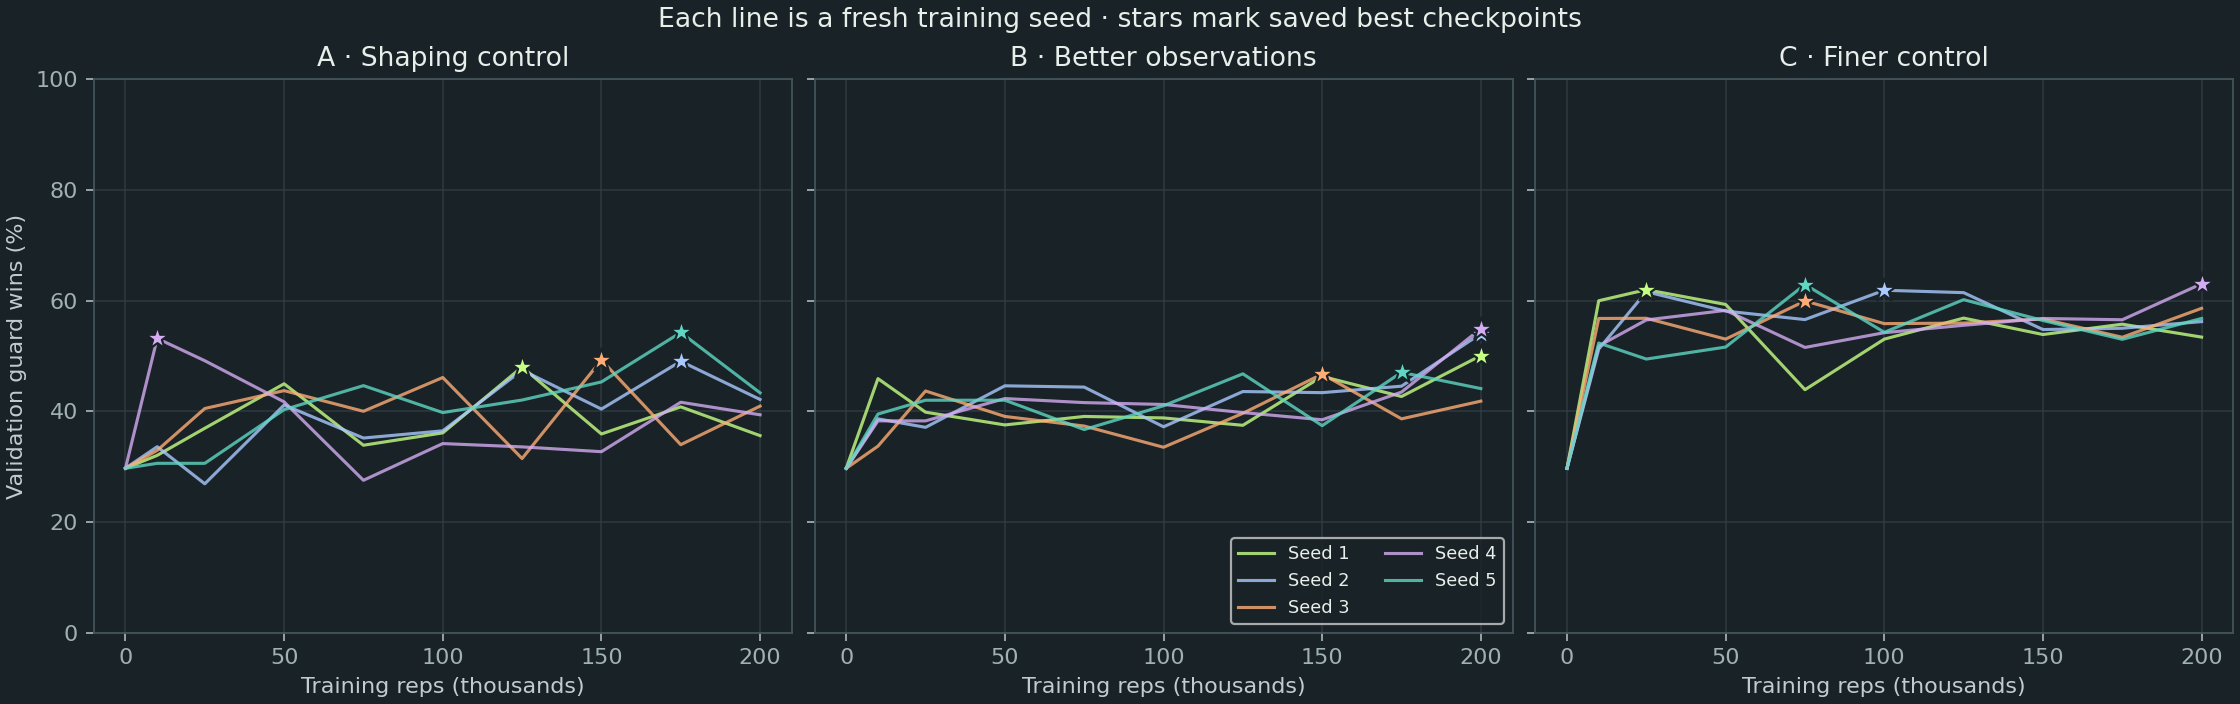
Ten snapshots per run, including zero training. At each snapshot, 3,000 fixed validation scenarios measure guard wins. The highest score wins; ties keep the earlier checkpoint. All 15 runs still complete exactly 200,000 training reps.
| Variant / training seed | Best at | Validation wins | Held-out best wins | Held-out final wins |
|---|
04 / MOVEMENT CHANGES
The guard can move anywhere within the field boundaries, including beside and behind the QB. Recovery steering rotates toward the DT–QB lane, contact eligibility follows that lane, and block escapes follow the direction of contact. Speed and acceleration still limit how quickly the guard can recover.
Potential shaping now measures the protective cushion along the QB-to-DT direction. A valid position behind the QB receives the same depth reward as its equivalent in front. Reward weights, physical ratings and the training budget are unchanged.
| Best checkpoint · G wins | Previous rules | Free movement | Change |
|---|
Fresh policies under each ruleset, with matching training seeds and evaluation scenarios. This compares the combined movement, contact and geometry corrections; it does not isolate which correction caused a change.
| New best checkpoints | Left wins | Head-on wins | Right wins | Mean absolute L/R gap |
|---|
The absolute gap is calculated separately for each seed before averaging. All variants retain the previous study’s seeded directional tie correction.
05 / WHAT CHANGED
Current coarse observations and 1.7-yard lateral / 1.8-yard depth target offsets. Potential shaping rewards positioning progress alongside the existing win/loss outcome.
Adds four three-category signals: signed protection-lane error, guard lateral velocity, DT-relative lateral velocity, and closing speed. Movement choices and rewards match A.
Uses 0.6-yard target offsets in all four directions. Observations and rewards match A. Targets guide normal acceleration and movement; players are never teleported.
Each seed starts at zero reps with empty movement tables and zero-valued opening tactics. Training scenarios are matched across variants within a seed and disjoint across the five seeds. Only the G trains. The reference DT playbook and million-rep test opponent remain frozen.
G: 315 lb, strength 89, speed 72, technique 70. DT: 280 lb, strength 74, speed 87, technique 70. All variants share the new field movement, directional contact and pocket geometry. They keep the same reward weights, learning rates, exploration floors and 0.3s decision cadence. Potential shaping is 0.25 × [0.94 Φ(next) − Φ(current)], with terminal Φ = 0.
Best and final policies are evaluated on 6,000 scenarios each for the normal rush mix, recovery starts, a frozen million-rep DT, and authored steering. Authored steering disables only the guard’s learned movement while preserving its opening tactic. Test sets are disjoint from training and checkpoint validation.
The richer state table may need a different training budget. These five-seed results establish performance under this 200K-rep protocol, not a universal ranking of learning methods. Contact footwork remains authored.